What Is Statistical Analysis?
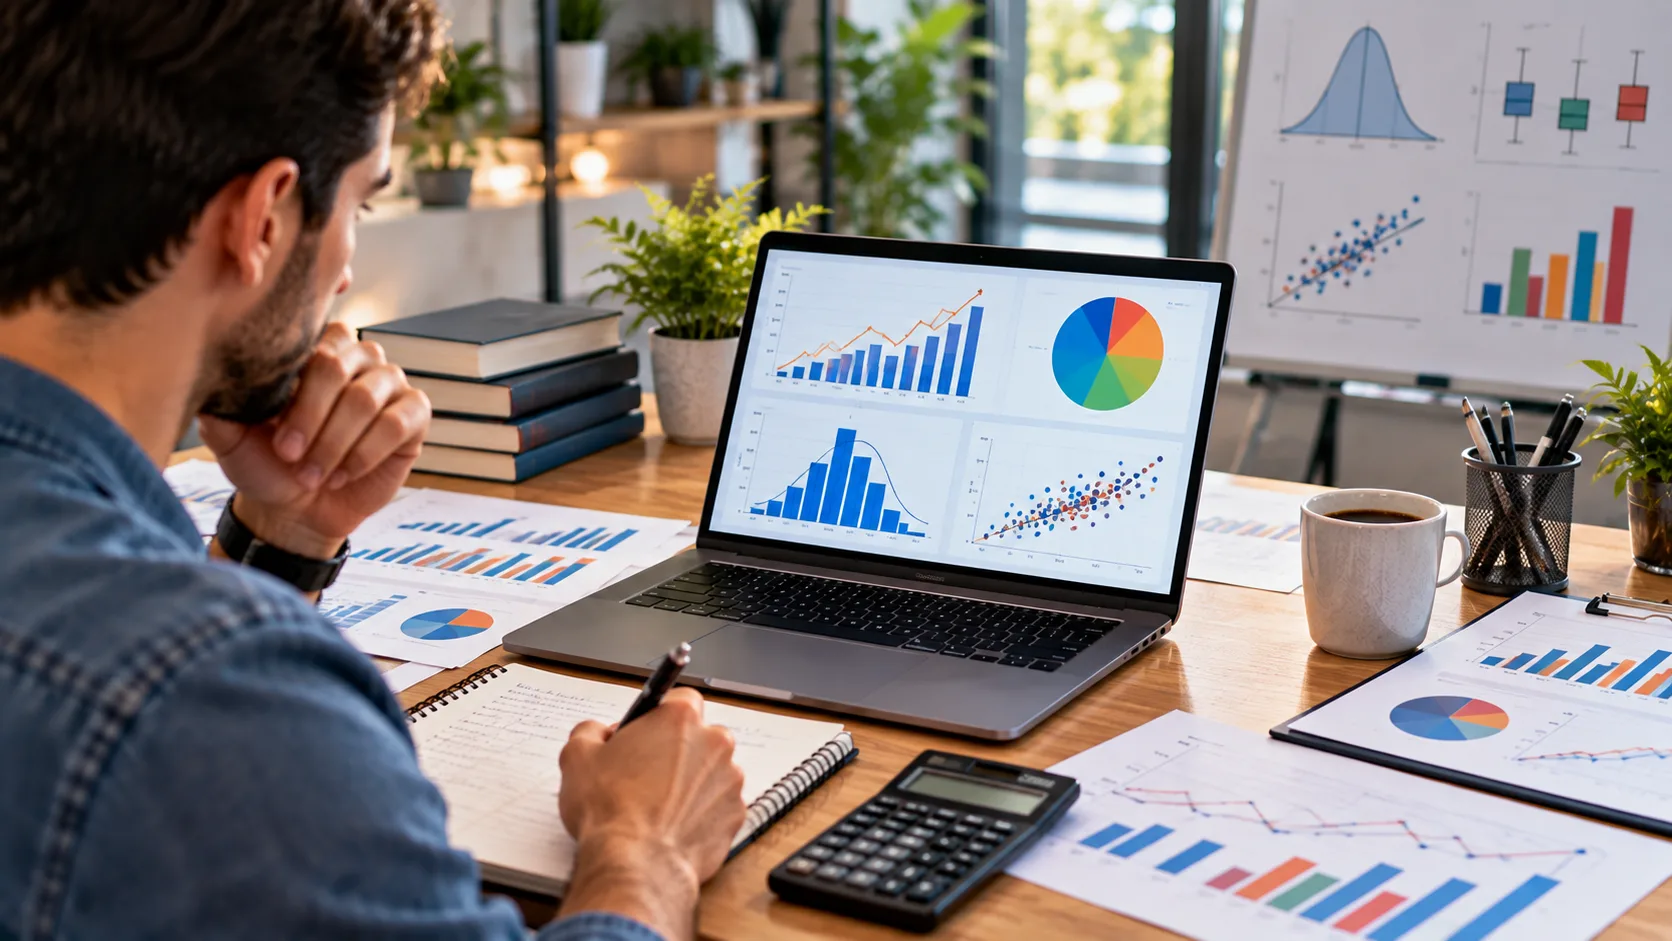
Statistical analysis is the process of collecting, organizing, examining, and interpreting data to discover meaningful patterns or relationships. It helps researchers, businesses, students, and professionals understand what information is actually showing instead of relying on assumptions. By applying statistical methods, large amounts of raw data can be transformed into conclusions that are easier to understand and use.
The process can involve simple calculations such as averages and percentages or more advanced techniques such as regression, hypothesis testing, and probability modeling. The appropriate method depends on the research question, type of data, sample size, and desired outcome. Good statistical analysis begins by clearly defining what you want to learn before choosing a calculation or software tool.
Statistics is used across fields such as healthcare, business, economics, education, marketing, technology, and social science. A company may analyze customer purchases, while a researcher might study survey responses or experimental results. In each case, statistical analysis helps turn observations into structured evidence that can support better decisions and clearer explanations.
Why Statistical Analysis Is Important
Statistical analysis helps people make decisions based on evidence instead of instinct alone. Organizations collect enormous amounts of data, but raw numbers provide limited value until they are interpreted properly. Statistical methods allow decision-makers to identify trends, compare groups, measure uncertainty, and determine whether observed differences are likely meaningful or simply the result of random variation.
Businesses use statistical analysis to understand customers, forecast demand, evaluate marketing campaigns, monitor quality, and measure financial performance. Researchers use it to test hypotheses and determine whether study findings are supported by available evidence. Governments and public organizations may analyze population, economic, health, or education data when planning programs and allocating resources.
Students also benefit from statistical thinking because it improves their ability to interpret reports, charts, financial information, and research findings. This is particularly useful in business-related subjects where data supports budgeting and performance decisions. Beginners developing wider financial knowledge may also find introductory accounting courses helpful alongside basic statistics.
Descriptive Statistical Analysis
Descriptive statistics summarizes the main features of a dataset without trying to make broader predictions about a larger population. Common descriptive measures include the mean, median, mode, range, variance, and standard deviation. Tables, percentages, charts, and frequency distributions are also frequently used to present data in a format that is easier to understand.
Imagine a teacher has exam scores from 40 students. Instead of reviewing every score individually, the teacher can calculate the average score, median result, highest score, lowest score, and overall spread. These measures quickly show how the class performed and whether most students achieved similar results or whether performance varied substantially.
Descriptive statistics is especially useful during the early stages of analysis because it helps analysts understand the structure of their data. Unexpected values, missing information, unusual distributions, or possible data-entry errors may become visible immediately. However, descriptive statistics only describes the observed dataset and does not automatically justify conclusions about people or cases outside that dataset.
Inferential Statistical Analysis
Inferential statistics uses data from a sample to draw conclusions or make estimates about a larger population. Researchers rarely have enough time or resources to collect information from every individual in a population. Instead, they select a suitable sample and use statistical techniques to estimate what may be true for the broader group.
For example, a company may survey 1,000 customers rather than contacting every person who has purchased from the business. If the sample is appropriately selected, the results can provide useful estimates of overall customer satisfaction. Confidence intervals and significance tests help analysts express how much uncertainty exists around those conclusions.
Inferential analysis requires careful attention to sampling quality because a biased sample can produce misleading conclusions. Sample size, selection method, variability, and assumptions behind each statistical test all matter. Analysts should therefore interpret inferential results with appropriate caution instead of treating every calculated percentage or statistical significance result as absolute proof.
Measures of Central Tendency
Measures of central tendency describe the central or typical value within a dataset. The three most common measures are mean, median, and mode. Each provides a different perspective, and the most useful measure depends on the type and distribution of the data being analyzed.
The mean is calculated by adding all values and dividing by the number of observations. The median is the middle value after arranging the data in order, while the mode is the value that appears most frequently. In a relatively balanced dataset without extreme values, the mean often provides a useful summary of the overall level.
The median can be more informative when extreme values strongly affect the average. For example, a few extremely high salaries can make the mean salary appear much higher than what most employees actually earn. Choosing the correct measure of central tendency prevents analysts from presenting a mathematically correct number that creates a misleading impression of typical results.
Measures of Variability
Measures of variability show how widely values are spread within a dataset. Two datasets can have exactly the same average while having very different levels of variation. Common measures include range, variance, standard deviation, and interquartile range, each of which provides information about how closely observations cluster around the center.
The range is calculated by subtracting the smallest value from the largest value, making it simple but highly sensitive to extreme observations. Standard deviation provides a more comprehensive measure by describing how far values typically fall from the mean. A smaller standard deviation generally indicates that observations are more tightly grouped around the average.
Understanding variability is important because averages alone can hide meaningful differences. Two stores might both average 500 daily customers, but one may consistently receive around 500 while the other fluctuates between extremely quiet and extremely busy days. Measuring variation reveals this difference and can support better staffing, forecasting, budgeting, and operational planning.
Correlation Analysis
Correlation analysis measures whether two variables tend to move together and how strong that relationship appears to be. A positive correlation means that both variables generally increase together, while a negative correlation means one tends to decrease as the other increases. A correlation close to zero suggests little or no linear relationship between the variables.
For example, a business might examine whether higher advertising expenditure is associated with increased sales. If both values rise together consistently, the data may show a positive correlation. Similarly, researchers could examine relationships between study time and test performance, temperature and electricity usage, or product price and demand.
Correlation does not prove that one variable causes the other. Two variables may move together because of another factor or simply due to coincidence. Analysts should therefore avoid turning correlation into a causal claim without additional evidence, experimental design, or deeper investigation into the mechanisms that could explain the observed relationship.
Regression Analysis
Regression analysis is used to examine how one or more independent variables are associated with a dependent variable. It can help explain relationships, estimate the influence of specific factors, and make predictions based on historical data. Linear regression is one of the most widely used forms because it models the relationship between variables using a fitted line.
A retailer could use regression analysis to study how sales are affected by advertising spending, price, seasonality, and store traffic. Instead of looking at each factor separately, regression allows multiple variables to be considered together. This can help analysts estimate which factors appear most strongly related to changes in the outcome being studied.
Regression results should still be interpreted carefully because a mathematical relationship does not automatically establish causation. Poor data quality, omitted variables, unusual observations, or incorrect assumptions can affect results significantly. Analysts should examine diagnostic information and understand the business or research context before using regression estimates for major decisions.
Hypothesis Testing
Hypothesis testing is a statistical method used to evaluate whether available sample evidence supports a particular claim. Analysts usually begin with a null hypothesis representing no difference or no effect and an alternative hypothesis representing the possibility of a meaningful difference. A statistical test is then used to determine how compatible the observed data is with the null hypothesis.
Suppose a company changes its checkout process and wants to determine whether conversion rates improved. The null hypothesis might state that the new design produces no meaningful difference, while the alternative suggests that conversion changed. Data from users experiencing each version can then be compared using an appropriate statistical test.
A p-value is commonly used during hypothesis testing, but it should not be treated as proof that a claim is true or false. It indicates how unusual the observed result would be under specified assumptions. Effect size, confidence intervals, study design, practical importance, and sample quality should also be considered when interpreting the outcome.
Parametric and Non-Parametric Methods
Parametric statistical methods make assumptions about the underlying distribution of data and often use parameters such as means and standard deviations. Common examples include the t-test, analysis of variance, and certain forms of regression. When their assumptions are reasonably satisfied, parametric methods can provide efficient and informative statistical estimates.
Non-parametric methods require fewer assumptions about the shape of the data distribution. They can be useful for ordinal data, small samples, heavily skewed distributions, or datasets containing unusual values that make standard assumptions inappropriate. Examples include the Mann-Whitney test, Wilcoxon signed-rank test, and Kruskal-Wallis test.
Neither category is automatically better than the other. The correct choice depends on the research question, data type, sample characteristics, and assumptions that can reasonably be justified. Analysts should examine their data before selecting a test rather than choosing a familiar method first and attempting to force the dataset to fit its requirements.
Qualitative and Quantitative Data in Statistical Analysis
Quantitative data consists of numerical values that can be measured or counted. Examples include age, income, temperature, sales revenue, website traffic, and test scores. Statistical calculations such as means, standard deviations, correlations, and regression models are commonly applied to quantitative variables because their numerical structure allows mathematical comparison.
Qualitative data describes categories or characteristics rather than measured numerical amounts. Examples include customer satisfaction categories, product types, employment status, geographic regions, and preferred brands. Although these variables are not numerical measurements, they can still be analyzed statistically using frequencies, percentages, contingency tables, and tests designed for categorical data.
Recognizing the type of data is important because it determines which statistical methods are appropriate. Calculating an average makes sense for numerical measurements but may be meaningless for category labels. Classifying variables correctly at the beginning of an analysis prevents inappropriate calculations and helps researchers choose techniques that genuinely match the information being studied.
Practical Examples of Statistical Analysis
Marketing teams frequently use statistical analysis to evaluate campaign performance. They may compare conversion rates between two landing pages, analyze customer acquisition costs across channels, or study whether certain audience characteristics are associated with higher purchase rates. These findings can help companies allocate advertising budgets toward strategies supported by stronger evidence.
In healthcare research, analysts may compare outcomes between treatment groups, examine relationships between risk factors and health conditions, or estimate how common a condition is within a population. Statistical methods help researchers separate meaningful patterns from random variation. Because healthcare decisions can have serious consequences, careful study design and interpretation are especially important.
Financial teams use statistics to examine revenue growth, expenses, customer behavior, investment performance, and forecasting trends. Educational institutions may analyze student achievement, attendance, and program outcomes, while manufacturers use statistics for quality control. These examples demonstrate that statistical analysis is not limited to academic research; it supports practical decision-making across many industries.
Steps in the Statistical Analysis Process
The first step in statistical analysis is defining a clear question. Analysts should know what they want to measure, compare, explain, or predict before collecting data. A vague question often leads to unnecessary calculations, while a well-defined objective makes it easier to determine which variables, sample, and statistical methods are actually needed.
Next, data must be collected, cleaned, and organized. This may involve correcting errors, handling missing values, checking for duplicates, identifying unusual observations, and ensuring variables are recorded consistently. Descriptive statistics and visualizations are usually useful at this stage because they reveal the overall shape and quality of the dataset before more advanced analysis begins.
Finally, analysts select appropriate methods, perform calculations, interpret results, and communicate findings. Conclusions should answer the original question while acknowledging important limitations or uncertainty. Effective analysis is not simply about producing numbers; it involves explaining what those numbers mean, how confident we can be, and what decisions they may reasonably support.
Conclusion
Statistical analysis provides a structured way to understand data and make evidence-based decisions. Techniques such as descriptive statistics, inferential analysis, correlation, regression, and hypothesis testing help analysts answer different types of questions. The best method depends on the data, research objective, assumptions, and level of uncertainty involved.
Understanding measures such as mean, median, standard deviation, and correlation builds a strong foundation for more advanced statistical work. However, calculations alone are not enough. Analysts must also consider sample quality, data type, study design, potential bias, and whether a statistically noticeable result is meaningful in the real-world context.
Whether you are working in business, research, finance, education, healthcare, or technology, statistical literacy can improve how you interpret information. Start with a clear question, choose appropriate methods, and communicate results carefully. When statistical analysis is applied thoughtfully, raw data becomes a powerful resource for understanding patterns, testing ideas, and supporting better decisions.
FAQs
What is statistical analysis in simple words?
Statistical analysis means collecting and examining data to understand patterns, differences, relationships, or trends. It uses mathematical methods to turn raw information into conclusions that can support research and decision-making.
What are the main types of statistical analysis?
The two broad types are descriptive and inferential statistics. Descriptive methods summarize observed data, while inferential methods use samples to estimate, compare, or draw conclusions about larger populations.
What is an example of statistical analysis?
A company comparing customer conversion rates before and after changing its website is performing statistical analysis. It can calculate percentages and apply a statistical test to evaluate whether the observed difference is meaningful.
What is the difference between correlation and regression?
Correlation measures the strength and direction of a relationship between variables. Regression goes further by modeling how one or more variables relate to an outcome and can also be used for prediction.
Why is statistical analysis important in business?
Statistical analysis helps businesses understand customers, evaluate marketing, forecast demand, monitor performance, and compare alternatives. It allows managers to make decisions using measurable evidence rather than relying entirely on assumptions or intuition.