Understanding the difference between discrete and continuous data is an important part of statistics, data analysis, mathematics, research, and business reporting. Both types belong to quantitative data, but they behave differently and are collected in different ways. Knowing how to identify them helps you choose suitable charts, statistical methods, measurement techniques, and analytical approaches.
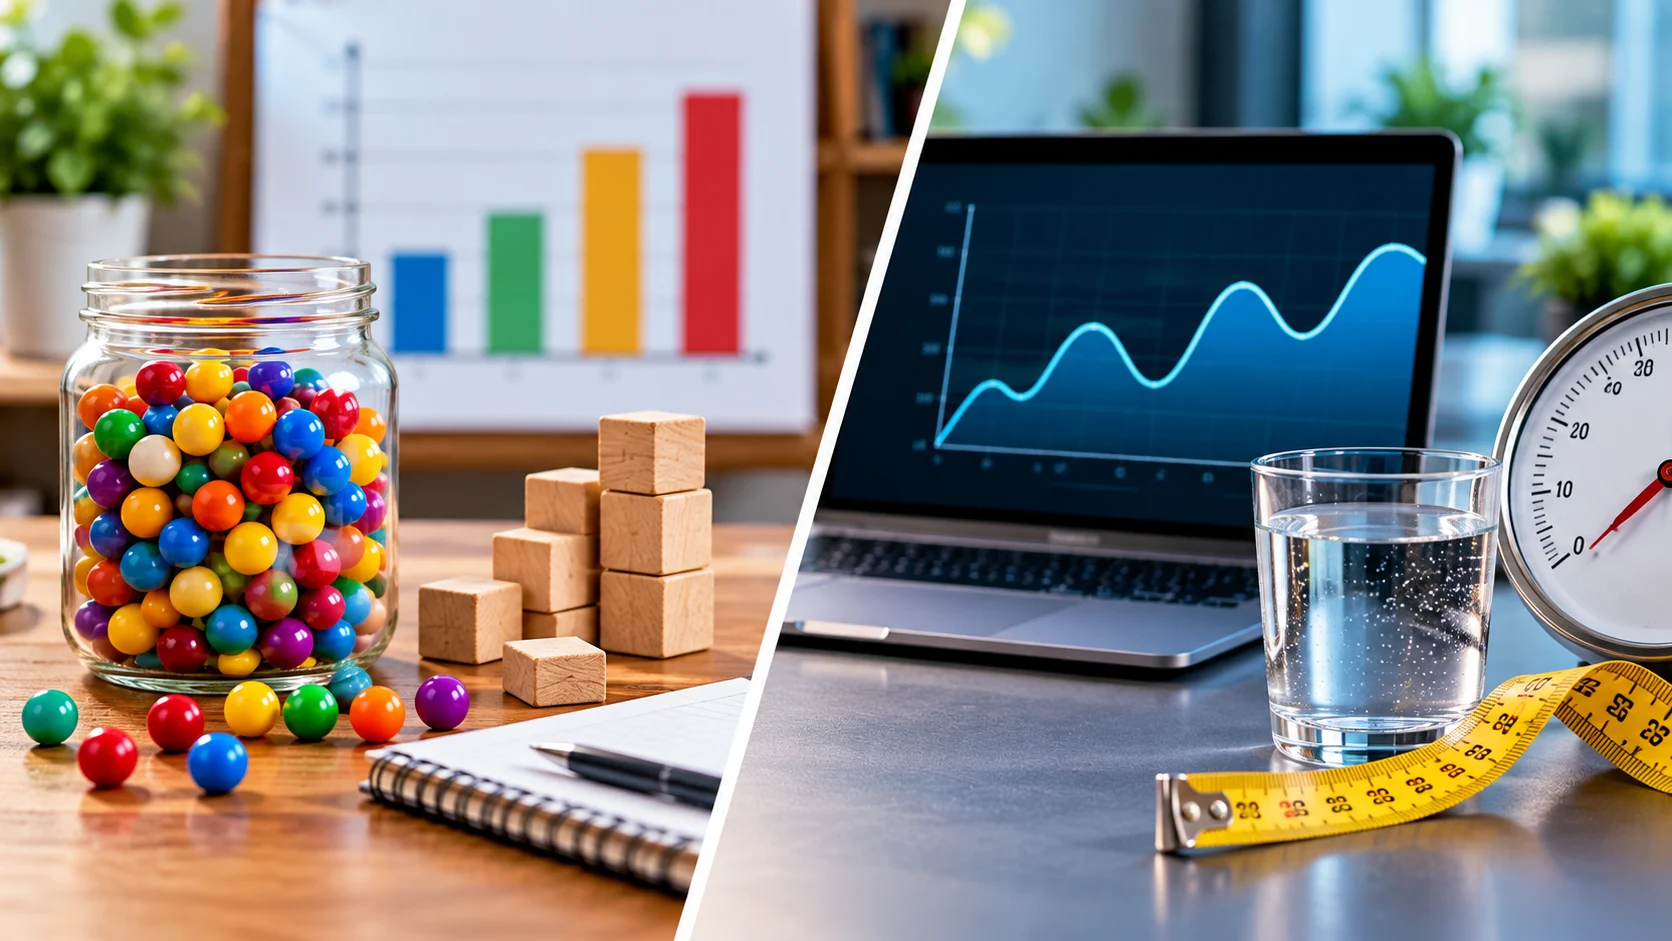
Discrete data represents values that can usually be counted as separate individual units, while continuous data represents values that can be measured across a range. For example, the number of students in a classroom is discrete because you can count each student. A student’s height, however, is continuous because it can take many possible values within a measurement range.
Although the distinction may sound simple, students and beginners often confuse the two when working with real-world examples. This guide explains discrete vs continuous data in clear language, covers their major differences, provides practical examples, and shows why correctly classifying numerical data matters in statistics and everyday decision-making.
What Is Discrete Data?
Discrete data is quantitative information that consists of separate, countable values. These values usually represent whole numbers because the items being measured cannot meaningfully be divided into smaller units. For example, the number of cars in a parking lot might be 20 or 21, but it would not normally be 20.5 cars.
The word discrete essentially means separate or distinct. Each value stands independently from the next possible value, meaning there may be gaps between observations. Examples include the number of employees in a company, the number of books on a shelf, customer complaints received in a day, and goals scored in a football match.
Discrete variables commonly result from counting rather than measuring. When you ask “how many,” you are often dealing with discrete data. Because these values are countable and distinct, they are especially common in surveys, inventory management, education, sports statistics, ecommerce reporting, and operational data analysis.
What Is Continuous Data?
Continuous data is quantitative information that can take any value within a particular range. Unlike discrete data, continuous values are generally obtained through measurement and can include decimals or fractions. Height, weight, temperature, time, distance, and speed are common examples because each can theoretically be measured with increasing levels of precision.
For example, a person’s height might be recorded as 170 centimeters, 170.5 centimeters, or 170.53 centimeters depending on the measuring instrument. There are potentially unlimited values between two points. This ability to represent finer measurements is one of the defining characteristics of continuous data.
Continuous variables are common in science, engineering, medicine, manufacturing, finance, sports, and environmental research. Whenever a value changes gradually rather than in separate steps, it is often continuous. Questions such as “how much,” “how long,” “how heavy,” or “how fast” frequently involve continuous measurements.
Discrete vs Continuous Data: The Main Difference
The primary difference between discrete and continuous data is how the values are obtained and represented. Discrete data is counted and consists of separate values, while continuous data is measured and can take almost any value within a range. This distinction affects how data is collected, analyzed, and visualized.
Consider the number of customers entering a shop compared with the amount of time each customer spends inside. Customer count is discrete because there can be 10, 11, or 12 customers but not 10.7 customers. Time spent shopping is continuous because it might be 12 minutes, 12.4 minutes, or 12.43 minutes.
Another useful distinction involves possible values between observations. With discrete data, certain intermediate values may not exist or make practical sense. With continuous data, additional values can almost always exist between two measurements, limited primarily by the precision of the measuring instrument being used.
Examples of Discrete Data
One of the easiest ways to understand discrete data is to look at situations involving counts. The number of children in a family, employees in an office, computers in a classroom, products sold, website orders, or calls received by a customer service team are all discrete variables. Each value represents a complete countable unit.
Sports also provide many straightforward discrete data examples. Goals scored, yellow cards received, players on a team, matches won, and penalties awarded can all be counted individually. You would generally record a team as scoring two or three goals rather than 2.6 goals during a match.
Business data frequently includes discrete variables as well. Companies may track customer complaints, completed purchases, product returns, support tickets, employee absences, and new subscribers. These values are useful for operational reporting because managers can compare clear counts across departments, time periods, products, or campaigns.
Examples of Continuous Data
Continuous data appears whenever values are measured rather than simply counted. Common examples include height, weight, temperature, rainfall, distance, pressure, time, and speed. Each measurement can potentially be recorded at a more precise level depending on the equipment or method used.
Imagine measuring the weight of several packages. One package might weigh 2 kilograms, another 2.25 kilograms, and another 2.257 kilograms if a highly precise scale is used. There are countless possible measurements between two and three kilograms, making weight a continuous variable.
Time is another useful example of continuous data. A runner might finish a race in 12 seconds, 12.4 seconds, or 12.47 seconds. Although results are often rounded for convenience, the underlying variable remains continuous because time can theoretically be measured using increasingly smaller units.
Counting vs Measuring
A simple way to distinguish discrete and continuous data is to ask whether the value is counted or measured. Discrete variables are usually obtained by counting individual items or occurrences. Continuous variables are normally obtained through measurement using tools such as scales, thermometers, rulers, clocks, or sensors.
For example, if you count the number of packages delivered during a day, you are collecting discrete data. If you measure the weight of each package, you are collecting continuous data. The first variable consists of separate whole units, while the second may include many decimal values.
This counting-versus-measuring rule is helpful but should not be applied mechanically. Some data may be recorded as whole numbers even though the underlying variable is continuous. Age, for instance, may be recorded as 30 years, but a person’s actual age changes continuously through months, days, hours, and seconds.
Whole Numbers and Decimal Values
Discrete data frequently appears as whole numbers because it represents complete individual units. You can have six customers, nine computers, or twenty employees. Fractions are often meaningless in these situations because part of a person, computer, or completed transaction would not represent the same counted item.
Continuous data commonly includes decimal values because measurements can fall between whole numbers. A temperature could be 22.4 degrees, a distance could be 5.7 kilometers, and a product could weigh 1.85 kilograms. Greater measurement precision can produce even more decimal places.
However, decimals alone do not always determine whether data is continuous. Some discrete variables can be expressed using decimals if the categories themselves allow them, while continuous measurements may be rounded to whole numbers. The underlying nature of the variable matters more than the way the value happens to be displayed.
Range of Possible Values
Discrete variables usually have a countable set of possible values. The values may be finite, such as the number of students in a particular classroom, or theoretically unlimited, such as the number of website visits over a long period. Even when the range is large, individual values remain distinct.
Continuous variables have infinitely many potential values within an interval. Between 10 and 11 meters, for example, measurements such as 10.1, 10.25, 10.567, and many others are possible. Increasing the precision of the measuring tool allows researchers to identify increasingly detailed values.
This distinction is important in statistical analysis because it affects probability calculations and modeling techniques. Discrete probability distributions focus on specific countable outcomes, while continuous probability distributions describe ranges of possible values. Choosing the correct approach depends on the structure of the variable being analyzed.
How Discrete and Continuous Data Are Collected
Discrete data is commonly collected through counting, surveys, digital tracking systems, transaction records, and administrative databases. A retailer might count daily purchases, while a school records the number of students attending each class. These observations can often be recorded directly without specialized measuring equipment.
Continuous data usually requires some form of measurement. Researchers may use thermometers, measuring tapes, laboratory instruments, GPS devices, timers, weighing scales, or automated sensors. The precision of the collected data depends partly on the quality and accuracy of the measurement method being used.
Modern digital systems can collect both types simultaneously. A fitness tracker, for example, may record the number of steps taken as discrete data while tracking distance, heart rate intervals, speed, or exercise duration as continuous measurements. Understanding each variable helps analysts interpret the resulting dataset correctly.
How Discrete and Continuous Data Are Visualized
Discrete data can be effectively displayed using bar charts, frequency tables, dot plots, and similar visualizations that emphasize separate categories or values. Bars are often separated to reinforce the idea that each value represents a distinct outcome. These visualizations make counts and frequencies easy to compare.
Continuous data is commonly represented using histograms, line graphs, density plots, or frequency distributions. Histograms group continuous measurements into intervals so analysts can examine how values are distributed. Because continuous values flow across a range, the bars in a histogram typically touch one another.
Choosing an appropriate data visualization improves interpretation and prevents misleading comparisons. A graph should reflect the structure of the underlying variable rather than simply looking attractive. Correct visualization helps readers recognize patterns, clusters, variation, trends, and unusual observations more accurately.
Why the Difference Matters in Statistics
Distinguishing between discrete and continuous data helps determine which statistical methods are appropriate. Some probability models are designed specifically for discrete counts, while others are intended for continuous measurements. Using the wrong assumptions can produce misleading results even when the calculations themselves are performed correctly.
For example, the binomial and Poisson distributions are commonly associated with discrete outcomes or event counts. The normal distribution is frequently used when modeling continuous measurements, although whether it is suitable depends on the actual distribution of the data. Understanding variable type is therefore an important first step before statistical modeling.
The distinction also influences summaries such as averages, frequency distributions, and probability statements. Analysts need to understand what individual numbers represent before drawing conclusions from them. Correct classification improves data quality, statistical interpretation, research design, and communication of results.
Discrete and Continuous Variables in Research
Researchers classify variables early in a study because variable type affects how information should be collected and analyzed. A study might record the number of hospital visits as a discrete variable while measuring each patient’s waiting time as a continuous variable. Both variables may contribute different insights to the same research question.
Clear classification also helps researchers select appropriate survey questions and measurement tools. A question about the number of purchases requires a count, while a question about the amount of money spent involves measurement. Defining variables carefully reduces ambiguity and improves consistency throughout the dataset.
In academic reports, researchers should explain how important variables were measured or recorded. This allows readers to understand whether rounding, grouping, or measurement limitations could affect the results. Accurate definitions make statistical findings easier to evaluate and reproduce.
Discrete and Continuous Data in Business
Businesses regularly work with both discrete and continuous data when evaluating performance. Discrete business metrics may include orders, customers, employees, complaints, leads, returns, and website conversions. Continuous metrics may include revenue amounts, delivery times, customer wait times, transaction values, and product weights.
Combining these data types can provide stronger insights than considering either one alone. An ecommerce company might track the number of orders alongside average delivery duration. A call center might compare the number of calls received with the length of each customer conversation.
Recognizing the difference helps businesses choose appropriate dashboards and reporting methods. Count-based metrics are often displayed as totals or bar charts, while measurements may be summarized using averages, ranges, distributions, or trend lines. Correct presentation helps decision-makers interpret operational performance more accurately.
Common Mistakes When Identifying Data Types
A common mistake is assuming that every whole number represents discrete data. Continuous measurements are frequently rounded to whole numbers for convenience. Temperature recorded as 25 degrees is still continuous because the actual temperature could have been 25.1, 25.25, or another nearby value.
Another mistake is assuming that every decimal value must represent continuous data. The format of a number does not define its statistical type. Analysts should instead examine what the variable represents, how it was generated, and whether meaningful intermediate values can exist.
Age often causes confusion because it may be treated differently depending on the context. Exact age measured in years, months, days, and seconds is continuous, but age categories or completed years may be analyzed as discrete or categorical information. Understanding the measurement method prevents oversimplification.
How to Identify Discrete vs Continuous Data Quickly
Start by asking whether you are counting separate items or measuring an amount. If you are counting people, products, events, or occurrences, the variable is probably discrete. If you are measuring time, weight, distance, temperature, or another quantity across a range, it is probably continuous.
Next, ask whether meaningful values can exist between two neighboring observations. There cannot normally be 5.5 students between five and six students, so student count is discrete. There can easily be 5.5 meters between five and six meters, making distance continuous.
Finally, consider the underlying variable rather than how the numbers are written in a spreadsheet. Rounding, formatting, and software settings can hide the true nature of the data. Understanding what each value actually represents is the most reliable way to classify it correctly.
Conclusion
Discrete and continuous data are both forms of quantitative data, but they represent numerical information in different ways. Discrete data consists of separate, countable values, while continuous data represents measurements that can take many possible values within a range. Understanding this distinction is fundamental to statistics and data analysis.
A practical rule is to think about counting versus measuring. Counts such as employees, purchases, goals, or complaints are usually discrete, while measurements such as height, time, temperature, and weight are usually continuous. However, always consider the underlying meaning of the variable rather than relying only on whether decimals appear.
Correctly identifying data types helps researchers, students, businesses, and analysts choose suitable statistical methods and visualizations. It also improves interpretation and reduces analytical mistakes. Once you understand the basic logic behind discrete vs continuous data, recognizing the difference in real-world datasets becomes much easier.
FAQs
What is the main difference between discrete and continuous data?
Discrete data consists of separate, countable values, while continuous data consists of measurable values across a range. The simplest distinction is that discrete data is usually counted, whereas continuous data is usually measured.
Is age discrete or continuous data?
Exact age is continuous because it changes through years, months, days, seconds, and smaller units. However, age recorded only as completed years may sometimes be treated as discrete for practical analysis.
Is height discrete or continuous data?
Height is continuous data because it can take many possible values within a range. A person’s height may be measured as 170 cm, 170.5 cm, or with even greater precision.
What are five examples of discrete data?
Examples include the number of students in a class, cars in a parking lot, customer orders, goals scored, and support tickets received. Each represents separate units that can be counted.
What are five examples of continuous data?
Common continuous data examples include height, weight, temperature, time, and distance. These variables are measured and can take many values, including decimals, within a particular range.